Alphabet is pushing deeper into voice artificial intelligence by launching Gemini 3.8 Live alongside advanced Flash and Flash-Lite text-to-speech models. This strategic rollout democratizes custom voice infrastructure, offering self-serve capabilities that challenge enterprise competitors like OpenAI.
By Nexvoro Tech Wire
PUBLISHED THU, SEP 24, 2026 10:45 PM UTC • 7 MIN READ
Alphabet Expands Voice AI Footprint with Gemini 3.8 Live
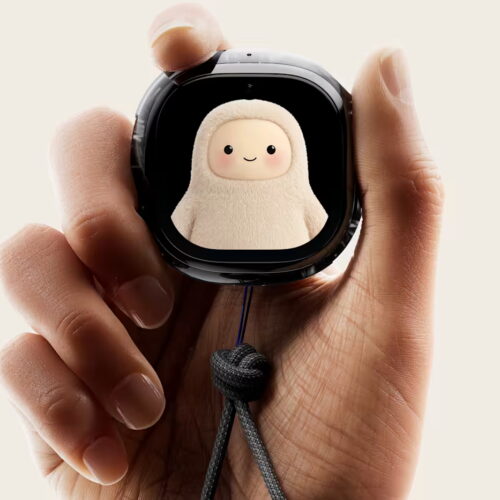
Alphabet is driving deeper into the rapidly evolving voice artificial intelligence landscape with the official introduction of Gemini 3.8 Live, a major technological upgrade that introduces a tangible face to Google's flagship AI ecosystem through the newly minted Live Avatar feature. As reported across leading technology desks, this sweeping rollout is designed to bridge the gap between abstract machine intelligence and deeply human-like, real-time audiovisual interaction. By equipping generative AI models with dynamic facial expressions and real-time responsiveness, Google is positioning its conversational ecosystem at the absolute forefront of multimodal computing.
The broader product suite accompanying this launch includes the specialized Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS models, engineered specifically to optimize ultra-low latency text-to-speech generation. According to official disclosures from the Google AI blog and tech industry trackers, these foundational upgrades fundamentally revolutionize how machines articulate thoughts, moving far beyond robotic cadence into nuanced, expressive vocal delivery that immediately says hello with striking natural inflection. This deep technical push underscores Alphabet's unwavering commitment to dominating the conversational AI sector across consumer and enterprise channels alike.
Self-Serve Architecture Disrupts Enterprise Voice Markets
In a strategic maneuver destined to send shockwaves through the enterprise software sector, Google has systematically undercut competitors by making advanced custom voice capabilities entirely self-serve. While industry rivals such as OpenAI have traditionally required enterprise clients to navigate lengthy sales pipelines, custom enterprise negotiations, and gatekept development channels to access bespoke voice architecture, Google's latest deployment empowers developers and organizations to spin up customized auditory experiences autonomously via streamlined cloud workflows.
This democratization of high-end synthetic speech infrastructure marks a pivotal turning point for software developers, customer service automation providers, and digital product designers worldwide. Market analysts tracking NASDAQ-listed Alphabet (GOOG) note that lowering the barrier to entry for cutting-edge text-to-speech and avatar integration accelerates enterprise adoption at an unprecedented scale. By eliminating friction in the deployment pipeline, Google is capturing vital developer mindshare and positioning its cloud ecosystem as the premier destination for next-generation interactive applications.
Product Architecture and Technical Capabilities
Under the hood, the Gemini 3.8 architecture represents a masterclass in efficiency and multimodal synchronization. The introduction of the Gemini 3.8 Flash TTS and Flash-Lite TTS variants demonstrates Google's keen focus on computational economy, ensuring that real-time vocal output does not compromise processing speed or inflate cloud infrastructure overhead. These models leverage advanced neural vocoder techniques to synthesize human speech with natural pauses, emotional resonance, and contextual pacing that mirrors authentic interpersonal dialogue.
Concurrently, the integration of the Live Avatar component requires immense computational synchronization between visual rendering pipelines and low-latency audio streams. Developers utilizing these tools can deploy interactive avatars that react instantaneously to user prompts, combining facial tracking, micro-expressions, and synchronized speech. This tight coupling of sight and sound transforms standard assistant interactions into immersive, face-to-face digital consultations, opening up transformative use cases in education, virtual healthcare, interactive entertainment, and automated customer support.
Competitive Pressures and Market Positioning
As the generative AI arms race intensifies, tech giants are increasingly vying to own the sensory layer of human-computer interaction. Voice and visual representation are the ultimate battlegrounds for consumer trust and corporate loyalty. By deploying Gemini 3.8 Live and its self-serve audio suite, Google is directly challenging prevailing industry norms and setting a new benchmark for accessibility, performance, and developer empowerment in the artificial intelligence economy.
Wall Street observers and tech industry pundits are closely monitoring how competitors will respond to Google's aggressive self-serve strategy. With Alphabet firmly pushing capital and engineering resources into voice AI innovation, the pressure is mounting across Silicon Valley to match these frictionless deployment models. Ultimately, the successful rollout of Gemini 3.8 Live signals that the future of computing will not only be intelligent - it will have a recognizable face and a naturally synthesized voice, seamlessly integrated into daily digital workflows.
Reporting synthesized under Nexvoro.tech Editorial Standards • Referenced via Google News US Technology
Verified Dispatch